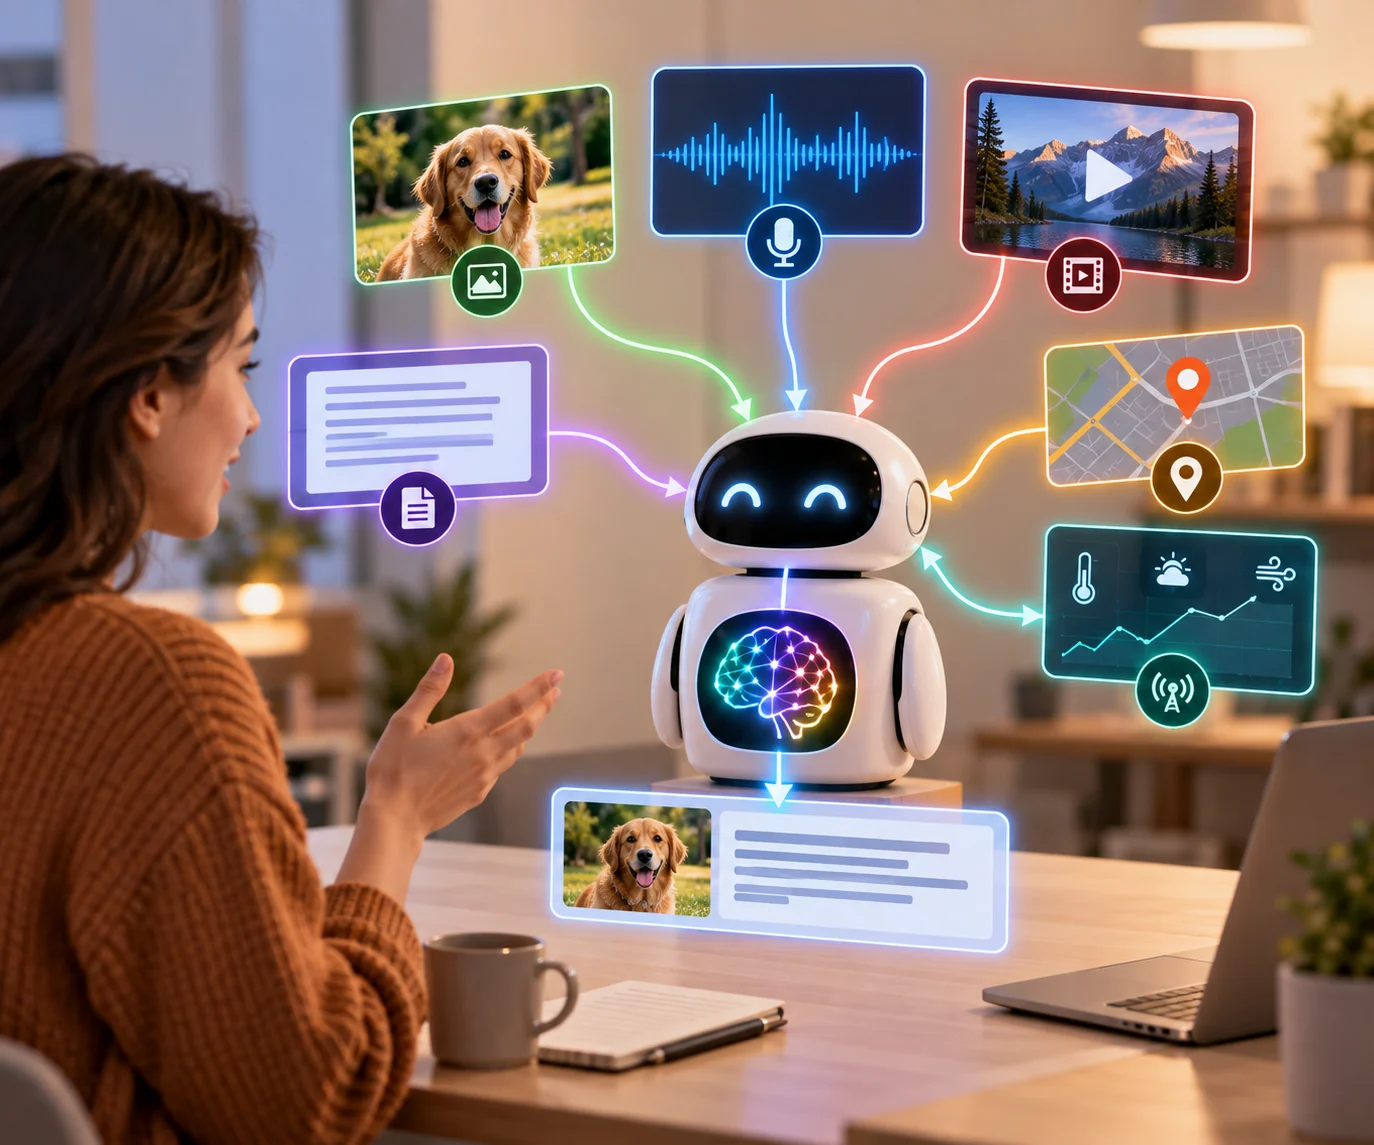
Multimodal AI is an artificial intelligence approach that can process and understand different types of information, such as text, images, audio, video, and sensor data. Instead of treating each input separately, it can connect information across formats to develop a broader understanding of a task. Depending on the system, different models or a shared architecture process these inputs and combine their outputs to generate predictions, responses, or actions.
For example, an AI assistant can analyze a photograph, understand a spoken question about it, and provide a relevant answer in text. This enables richer interactions and more capable automation. Applications include virtual assistants, healthcare, robotics, content analysis, and autonomous systems.