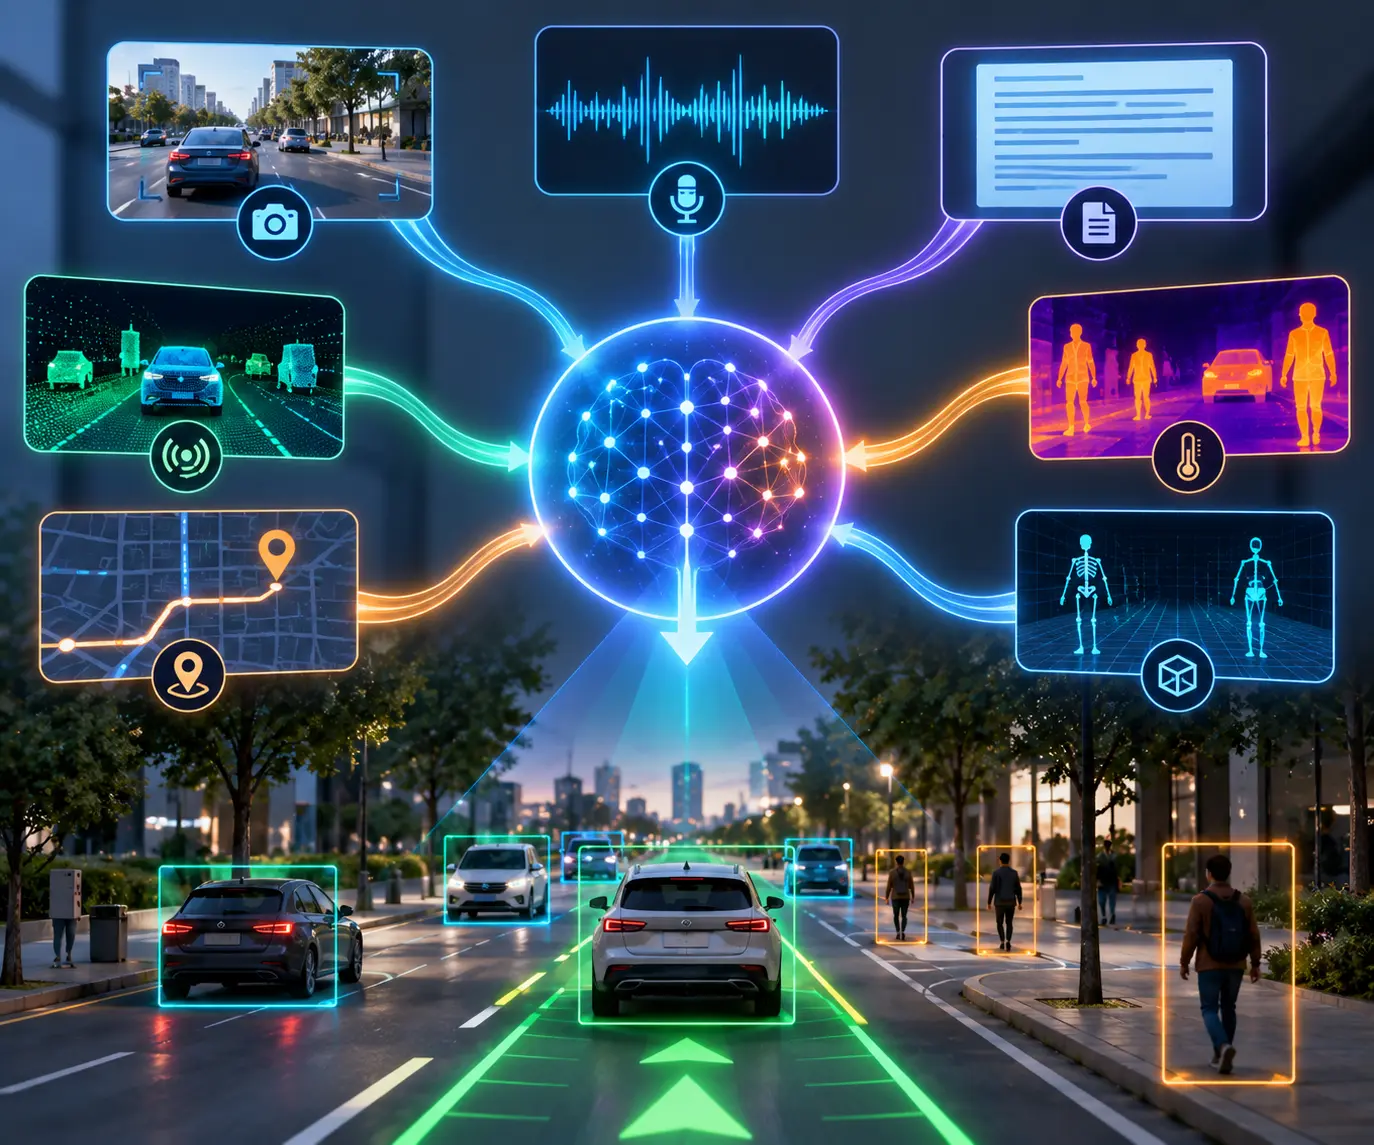
Multi-modal fusion is the process of combining information from different types of data, such as text, images, audio, video, or sensor readings, to help an AI system build a more complete understanding of a situation. The system processes these inputs individually or together and integrates their useful features, allowing it to make predictions, classifications, or decisions using information from multiple sources.
For example, an autonomous vehicle can combine camera images, radar measurements, and other sensor data to better understand nearby vehicles and road conditions. This can improve accuracy and reliability compared with relying on one data source. Multi-modal fusion is useful in robotics, healthcare, autonomous systems, security, search, and intelligent assistants.