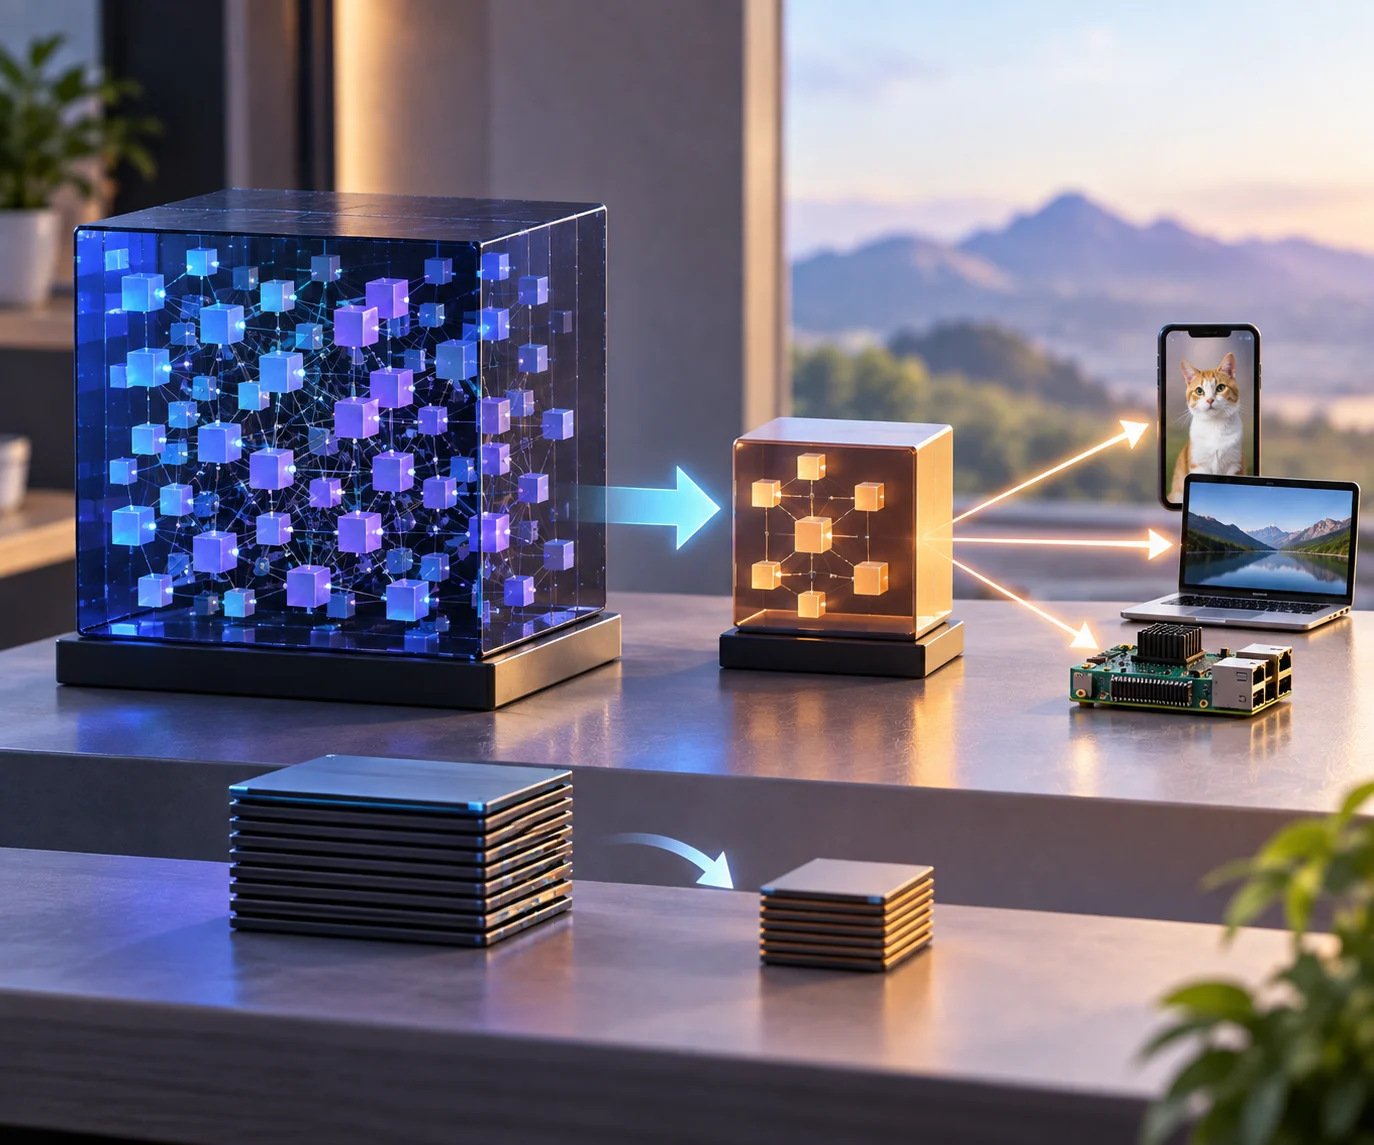
Model quantization is a technique that reduces the numerical precision used to represent a machine learning model’s weights and calculations. Instead of higher-precision formats such as 32-bit floating point, quantization can use lower-precision formats such as 16-bit or 8-bit values. This reduces model size and memory use and can improve inference speed, especially on suitable hardware.
For example, a mobile AI application can quantize a vision model so it runs efficiently on a smartphone with limited computing resources. It helps reduce storage and energy requirements, lower latency, and enable AI models to run on edge devices, embedded systems, and other resource-constrained environments.