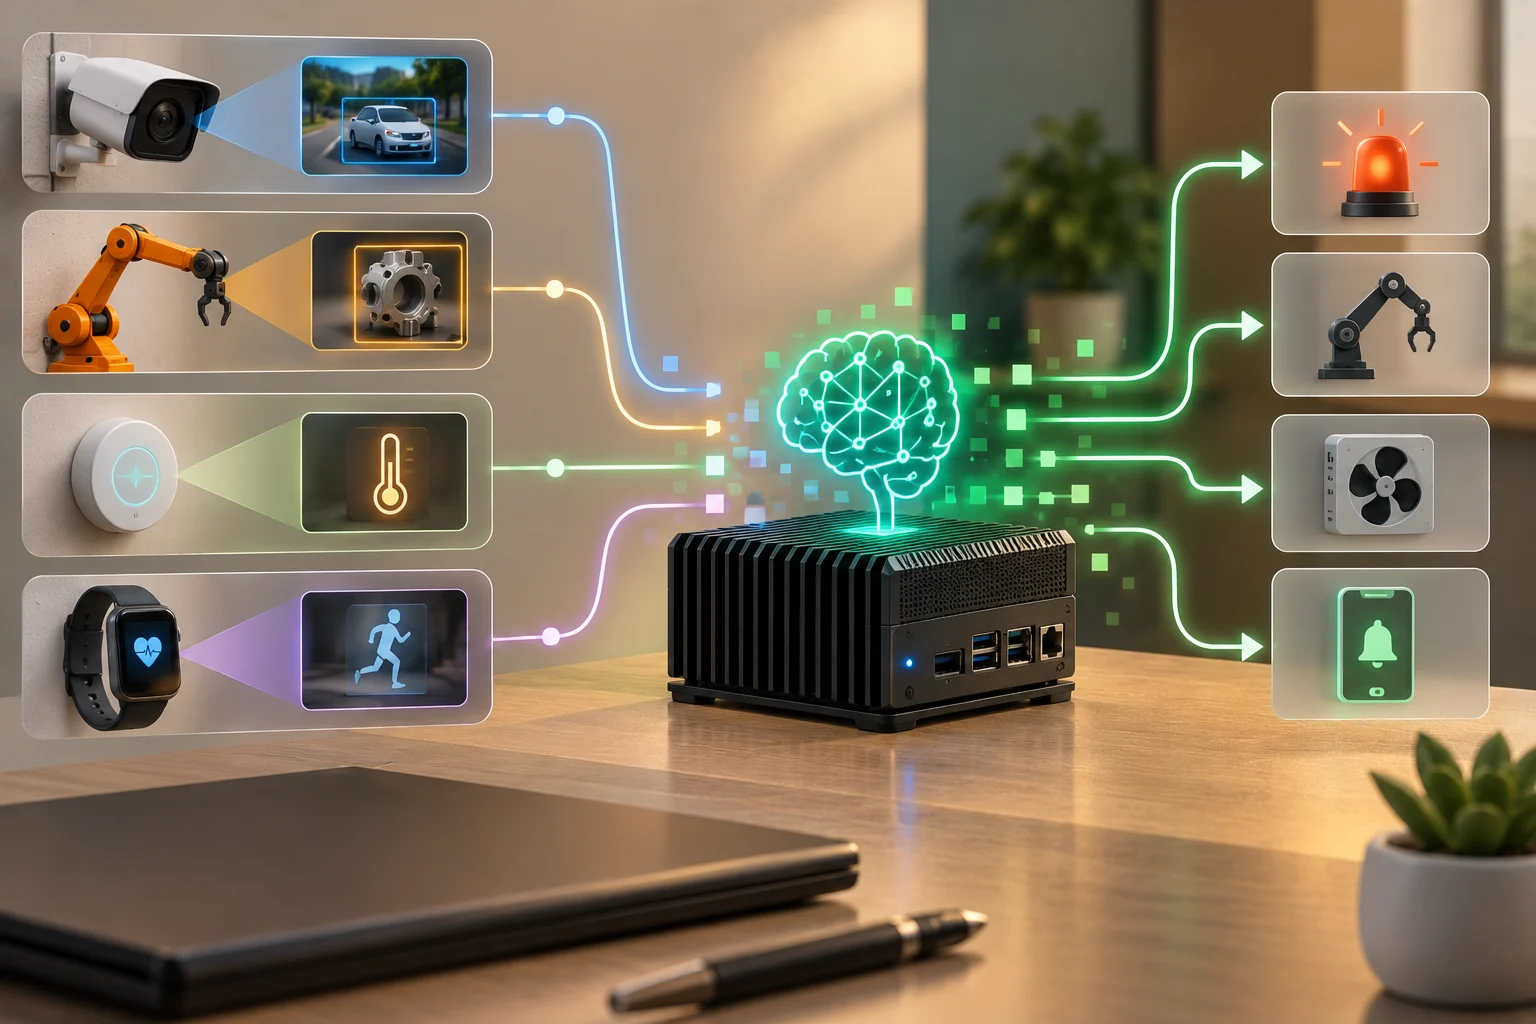
Micro Inference is the process of running small, optimized artificial intelligence models directly on devices with limited computing and memory resources. Instead of sending data to a remote cloud server for every prediction, the device performs inference locally, enabling faster responses while reducing network dependency and data transmission. These models are typically designed to use minimal processing power, memory, and energy.
For example, a smart camera can use a compact AI model to detect objects or identify unusual activity directly on the device. Because the analysis happens locally, the system can respond immediately without continuously uploading video to a cloud platform. Micro Inference is particularly useful for edge devices, embedded systems, IoT sensors, mobile applications, wearables, industrial equipment, and other environments where low latency, privacy, and resource efficiency are important.