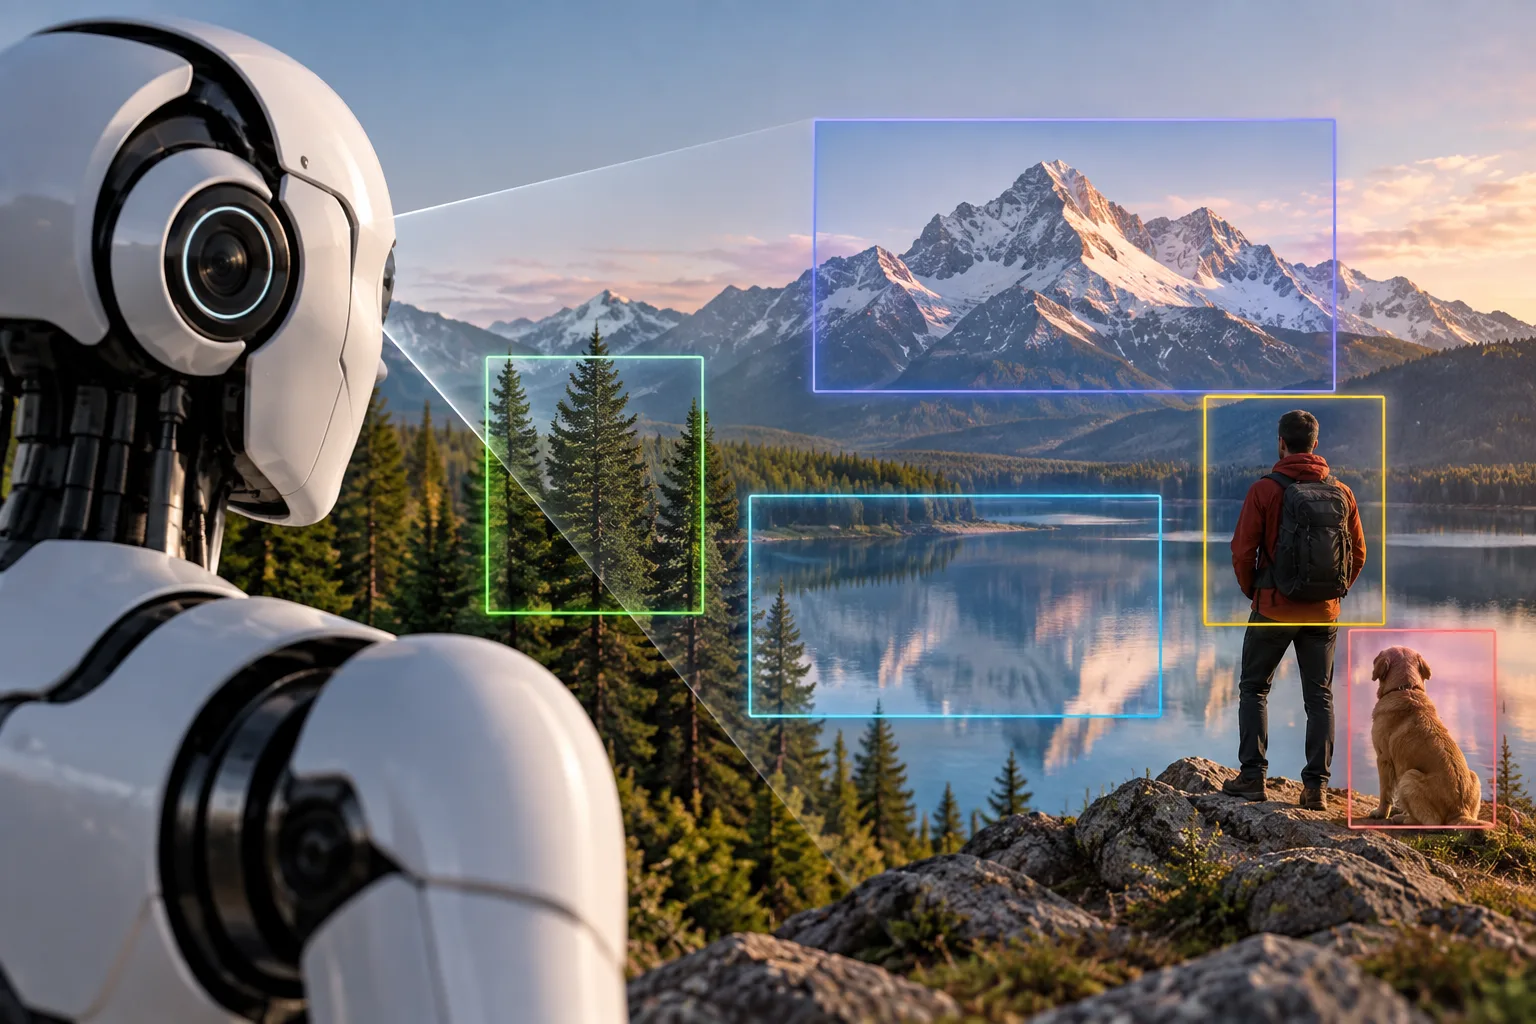
A Large Vision Model (LVM) is an artificial intelligence model designed to understand and interpret visual information such as images and video. It learns patterns from large collections of visual data and can identify objects, scenes, relationships, and other meaningful details. Depending on its design, it may combine visual understanding with language capabilities, allowing it to describe images, answer questions about visual content, or perform complex analysis.
For example, an LVM can examine medical images to help identify patterns that may require further review by healthcare professionals. It is useful for image analysis, visual search, robotics, autonomous systems, quality inspection, security, and document understanding, helping organizations process visual information more efficiently.