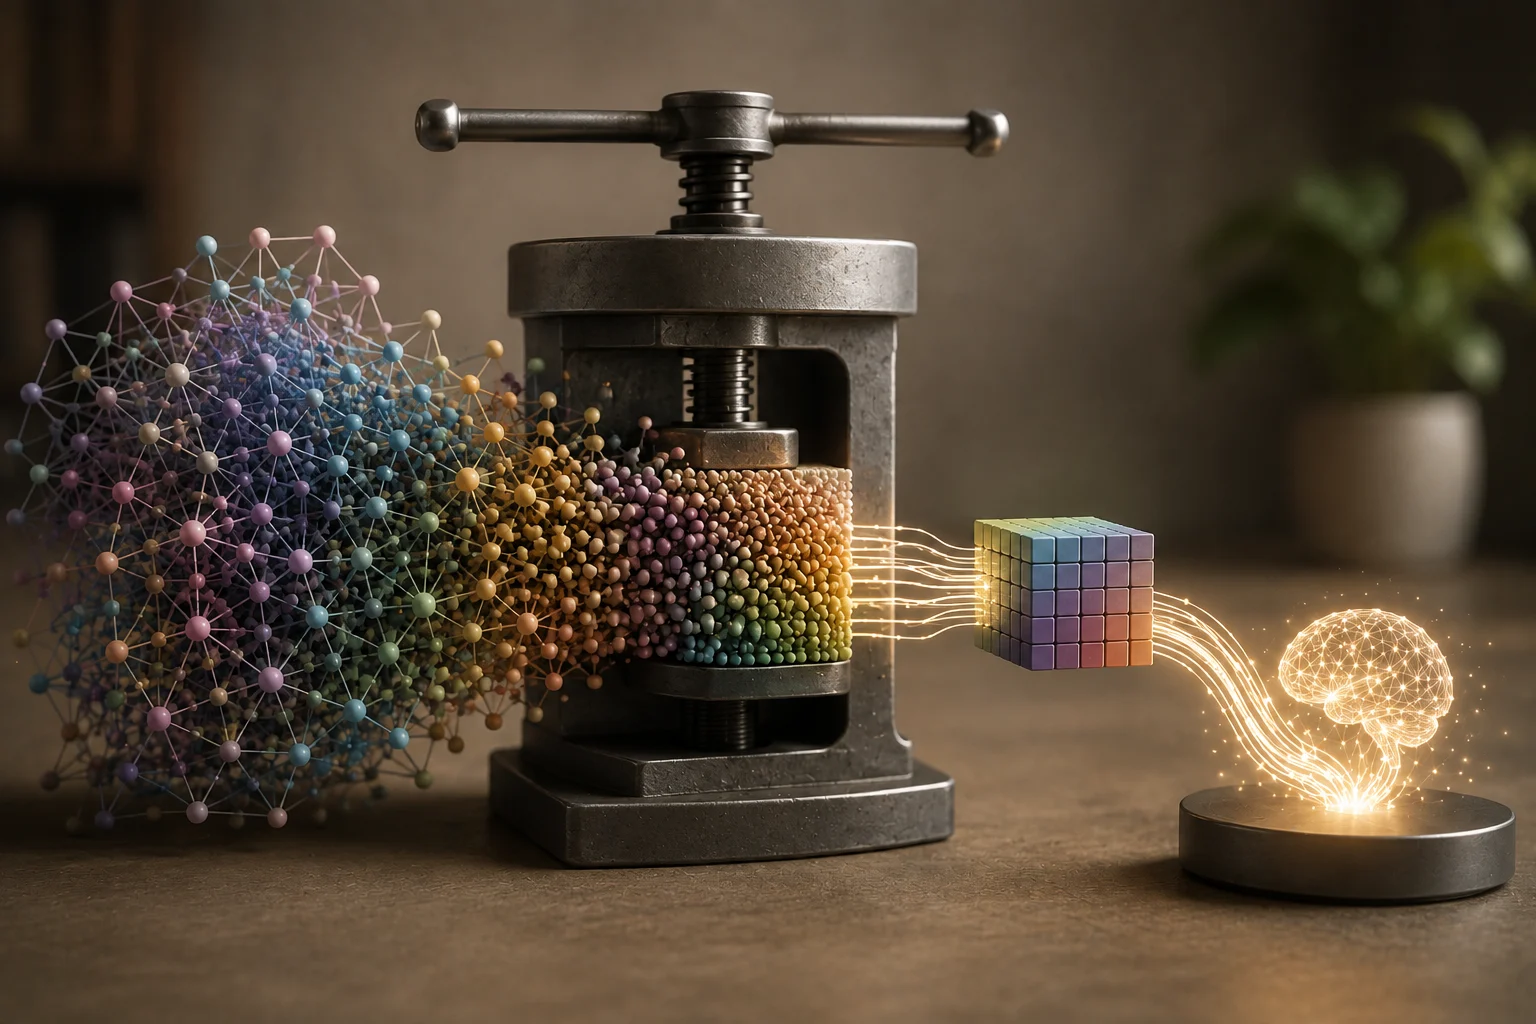
AI Model Compression is the process of reducing the size, computational requirements, or memory footprint of an artificial intelligence model while preserving as much of its predictive performance as possible. It makes large or complex models easier and faster to run on systems with limited computing resources.
Common techniques include quantization, pruning, knowledge distillation, and low-rank factorization. These methods are particularly useful for deploying AI on smartphones, edge devices, embedded systems, and cost-sensitive cloud environments, where lower memory use, faster inference, and reduced power consumption can be critical.