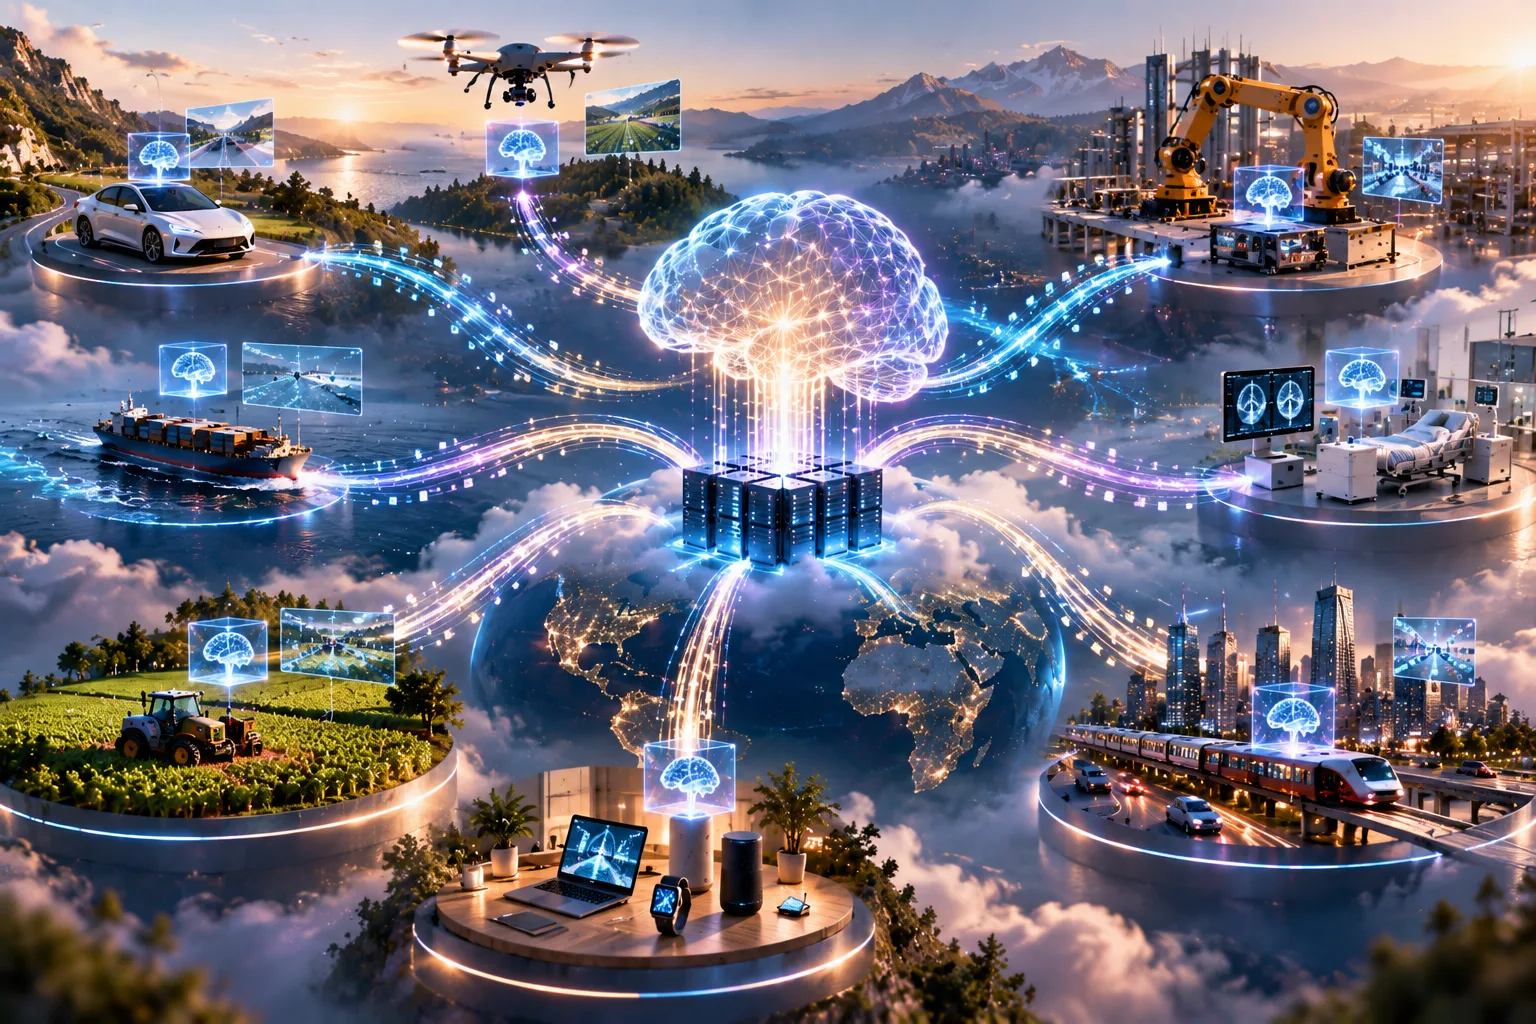
Distributed inference is the process of running an AI model across multiple connected devices, servers, or computing locations instead of relying on a single machine. The workload can be divided between systems, allowing different parts of the model or different inference requests to be processed simultaneously. This approach can improve scalability, reduce processing delays, and make better use of available computing resources.
For example, an AI application may process sensor data on edge devices while sending more complex computations to nearby servers or cloud infrastructure. Distributed inference is useful for applications that require fast responses or operate across many locations, such as autonomous systems, industrial monitoring, smart devices, and real-time analytics. Related concepts include edge AI, distributed computing, model parallelism, and federated learning