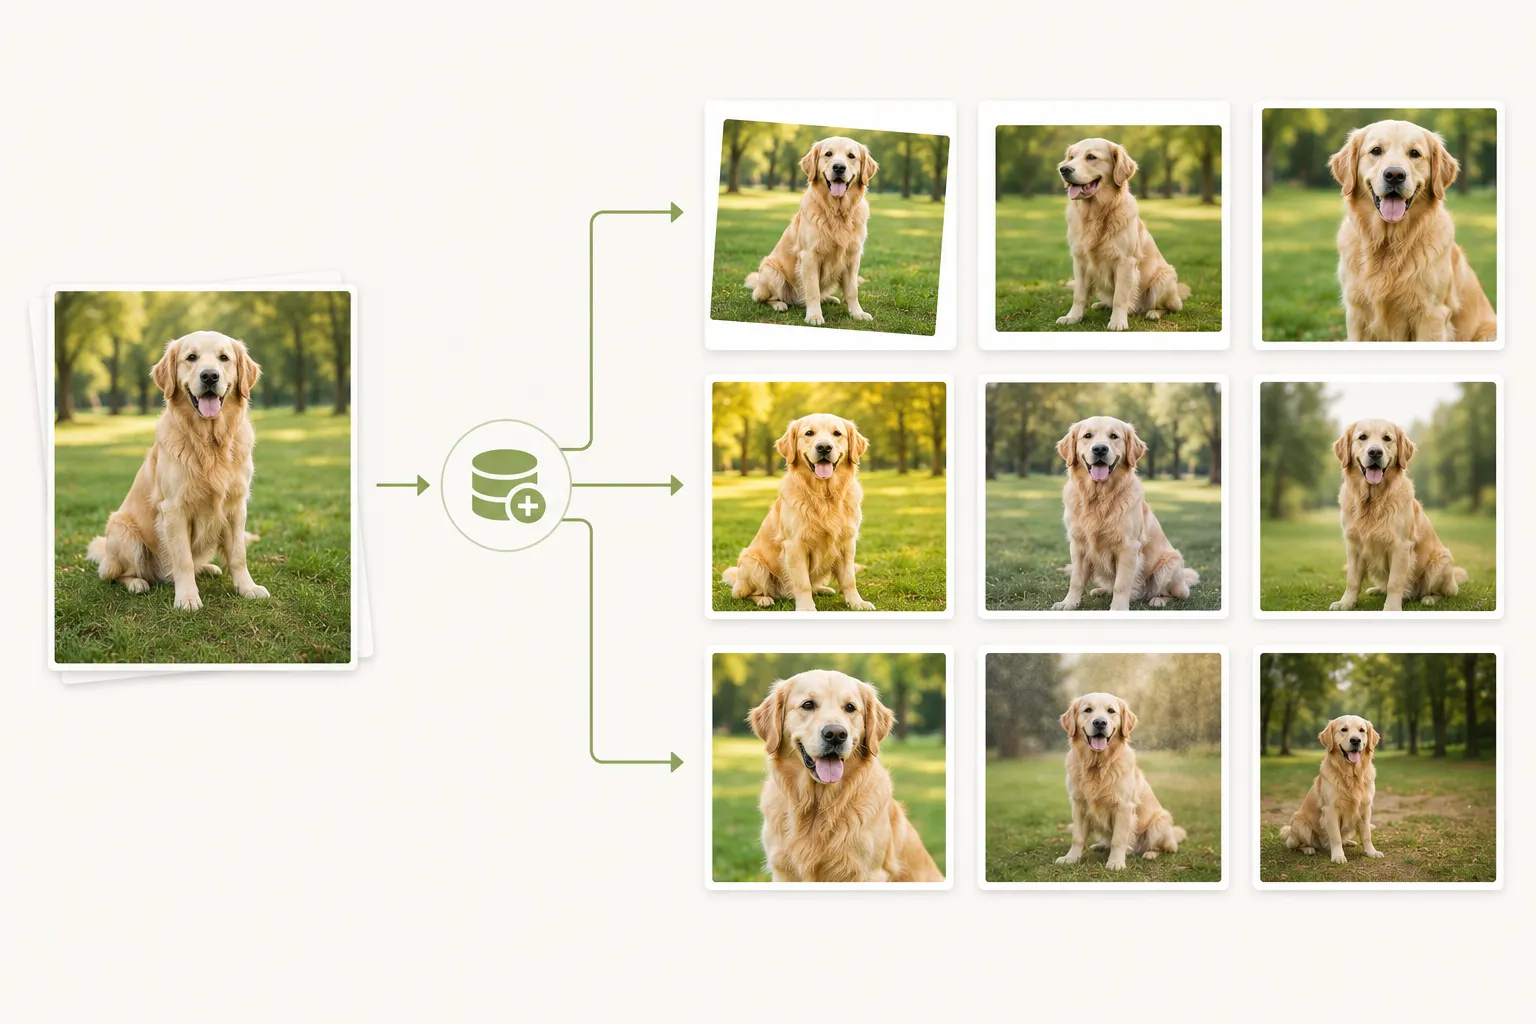
Data Augmentation is the process of creating additional training data by applying controlled modifications to existing datasets. It helps AI and machine learning models learn from greater variations of the same information without requiring every example to be collected manually. Common techniques include rotating, cropping, resizing, flipping, or adjusting the brightness of images, as well as modifying text or audio data.
Data Augmentation is widely used in computer vision, speech recognition, and natural language processing. By introducing realistic variations, it can improve model generalization, reduce overfitting, and make models more robust when they encounter new conditions. It is particularly useful when collecting large, diverse, and accurately labeled datasets is difficult or expensive.