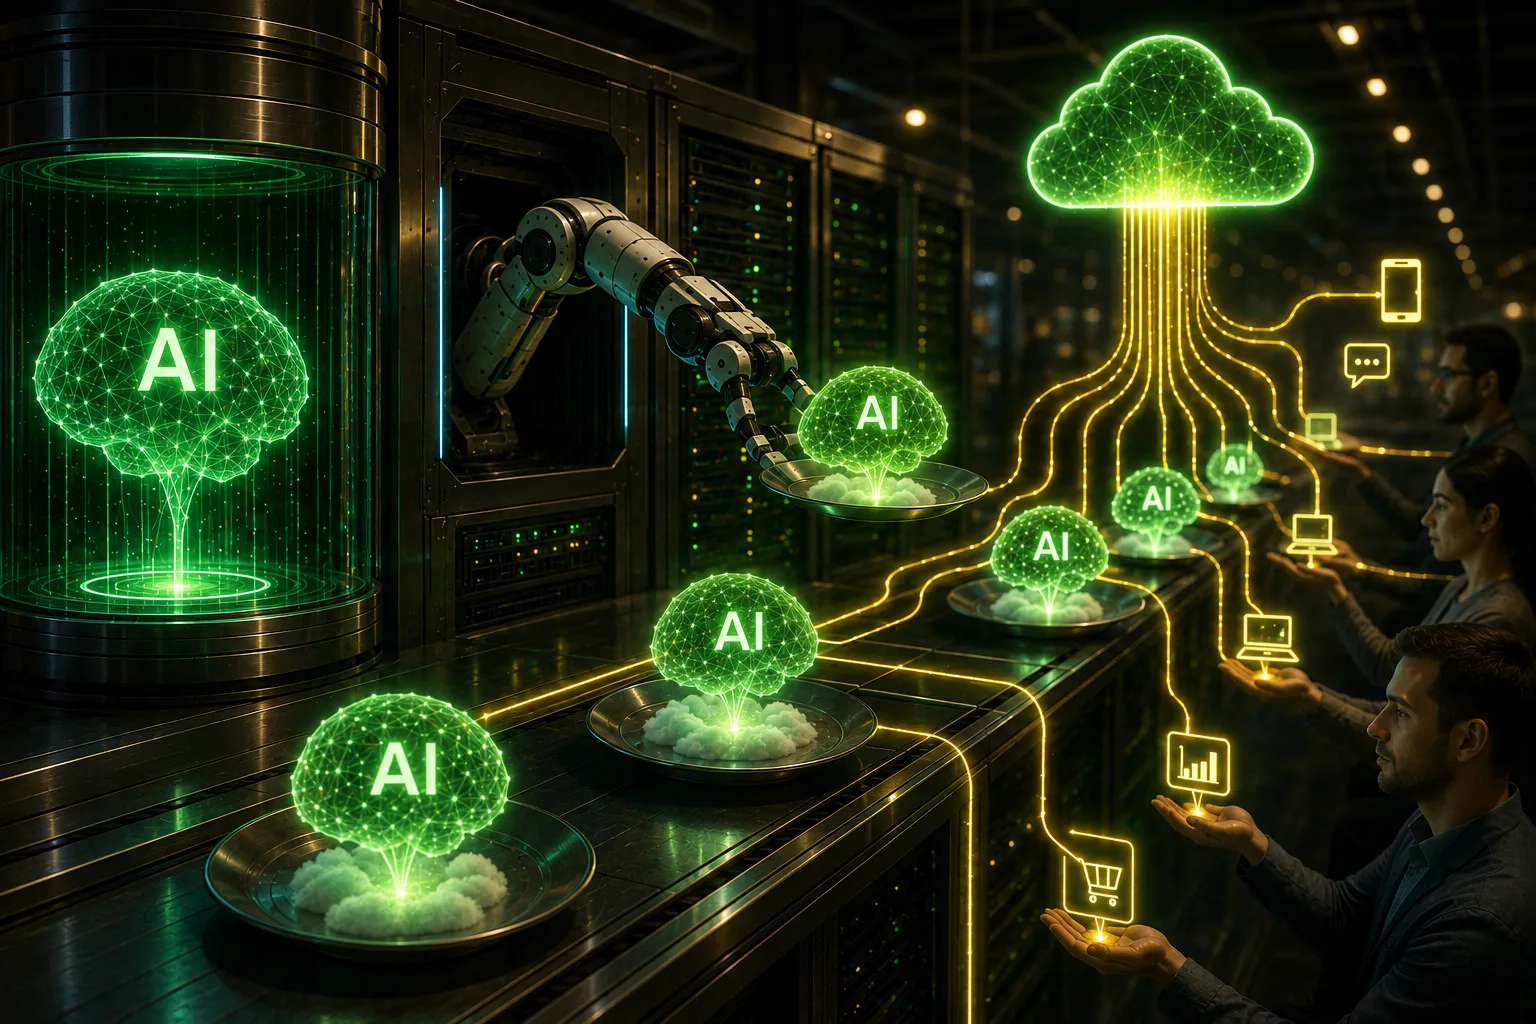
AI Model Serving is the process of making a trained artificial intelligence model available to applications so it can generate predictions or other outputs from new data. It involves packaging the model, providing an interface for requests, and managing the infrastructure required to run inference reliably at the required speed and scale.
Model-serving systems can support real-time APIs, batch processing, or streaming workloads and may run in cloud, on-premises, or edge environments. They often include features such as version management, request routing, autoscaling, monitoring, and hardware optimization, helping teams move models from development into dependable production use.